AudioBard
Open-source multi-voice audiobook generator from EPUB and TXT books.
Transform books into cast-narrated audiobooks with distinct, consistent voices assigned to each character — completely offline or via BYOK cloud models.
Motivation
Standard text-to-speech tools read entire books in a single robotic monotone voice without character distinction. Commercial voice platforms frequently require uploading private manuscripts to remote servers and charge recurring subscriptions.
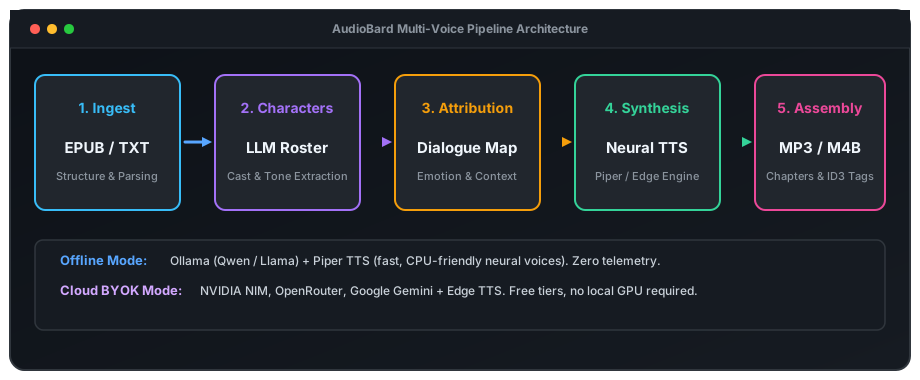
AudioBard provides a local-first alternative that automatically extracts character rosters, attributes dialogue with emotional context, and synthesizes audio tracks using neural TTS models.
Key Capabilities
- Character Extraction & Dialogue Attribution: Uses LLMs to detect speaking characters, track aliases across chapters, and determine vocal emotion.
- Multi-Voice Neural Synthesis: Automatically maps distinct voices (via Piper TTS or Edge TTS) to each character based on gender, age, and emotional tone.
- Offline & Cloud Modes: Complete local privacy with Ollama + Piper TTS (zero data leaves your machine), or cloud BYOK (NVIDIA NIM, OpenRouter, Google Gemini, Edge TTS) with your own API keys.
- Desktop GUI & CLI: Built with Tauri v2 + Vue 3, featuring drag & drop book ingestion, library player, and Spanish / English localization.
Comparison with Alternatives
| Feature | AudioBard | Commercial Cloud Platforms | Standard Reader TTS |
|---|---|---|---|
| Execution Environment | Local offline or Cloud BYOK | Cloud-hosted servers | Local device |
| Character Casting | Multi-voice per character | Manual studio configuration | Single narrator voice |
| Interfaces | Desktop GUI (Tauri) + CLI | Web dashboard only | Desktop or browser extension |
| Licensing & Cost | Open source (MIT), zero subscription fees | Subscription ($15–$100+/mo) | Free or bundled |
| Attribution Verification | Hermetic benchmark suite vs gold standard | Not published | Not applicable |
Documentation Navigation
- Overview & Architecture — Learn how AudioBard's 6-stage audio pipeline works under the hood.
- Installation Guide — Step-by-step setup for Python, Ollama, Piper, and Tauri.
- Quickstart Tutorial — Generate your first audiobook via GUI or CLI in under 5 minutes.
- Supported Providers — Detailed configuration for LLM and TTS backends (Ollama, Piper, Gemini, NIM, OpenRouter, Edge TTS).
- PDF2Bard Companion — Convert and clean PDF books for AudioBard ingestion.